Kimi K3.1 Pro targets longer coding and knowledge-work tasks
Moonshot launches K3.1 Pro with a million-token context window, new benchmark results, and model weights promised by November 4.
Moonshot AI has introduced Kimi K3.1 Pro, a multimodal model aimed at coding, 3D creation, and knowledge work. The company describes a mixture-of-experts architecture with 2.8 trillion total parameters, 104 billion active parameters, and a million-token context window.
The model is available through Kimi’s applications, Kimi Work, Kimi Code, and its API. A Highspeed variant is also available.
What the benchmarks show
Moonshot reports these results:
| Evaluation | K3.1 Pro score |
|---|---|
| Terminal-Bench 4.0 | 65.7% |
| Kimi Code Bench 3.0 Long-horizon, an internal evaluation | 61.2% |
| BenchCAD with tools | 92.7% |
| OfficeQA Pro v2 | 64.4 |
On Terminal-Bench 4.0, the report places Kimi below Claude Opus 5.5 at 66.4% and above GPT-6 Astra at 58.2%.
These are vendor-reported results. The comparison draws on multiple evaluation sources and setups, so it should not be read as an independent, uniform test or an overall ranking.
Original benchmark charts
Moonshot AI's benchmark overview. Vendor-reported results.
View full-size chart (opens in a new tab)
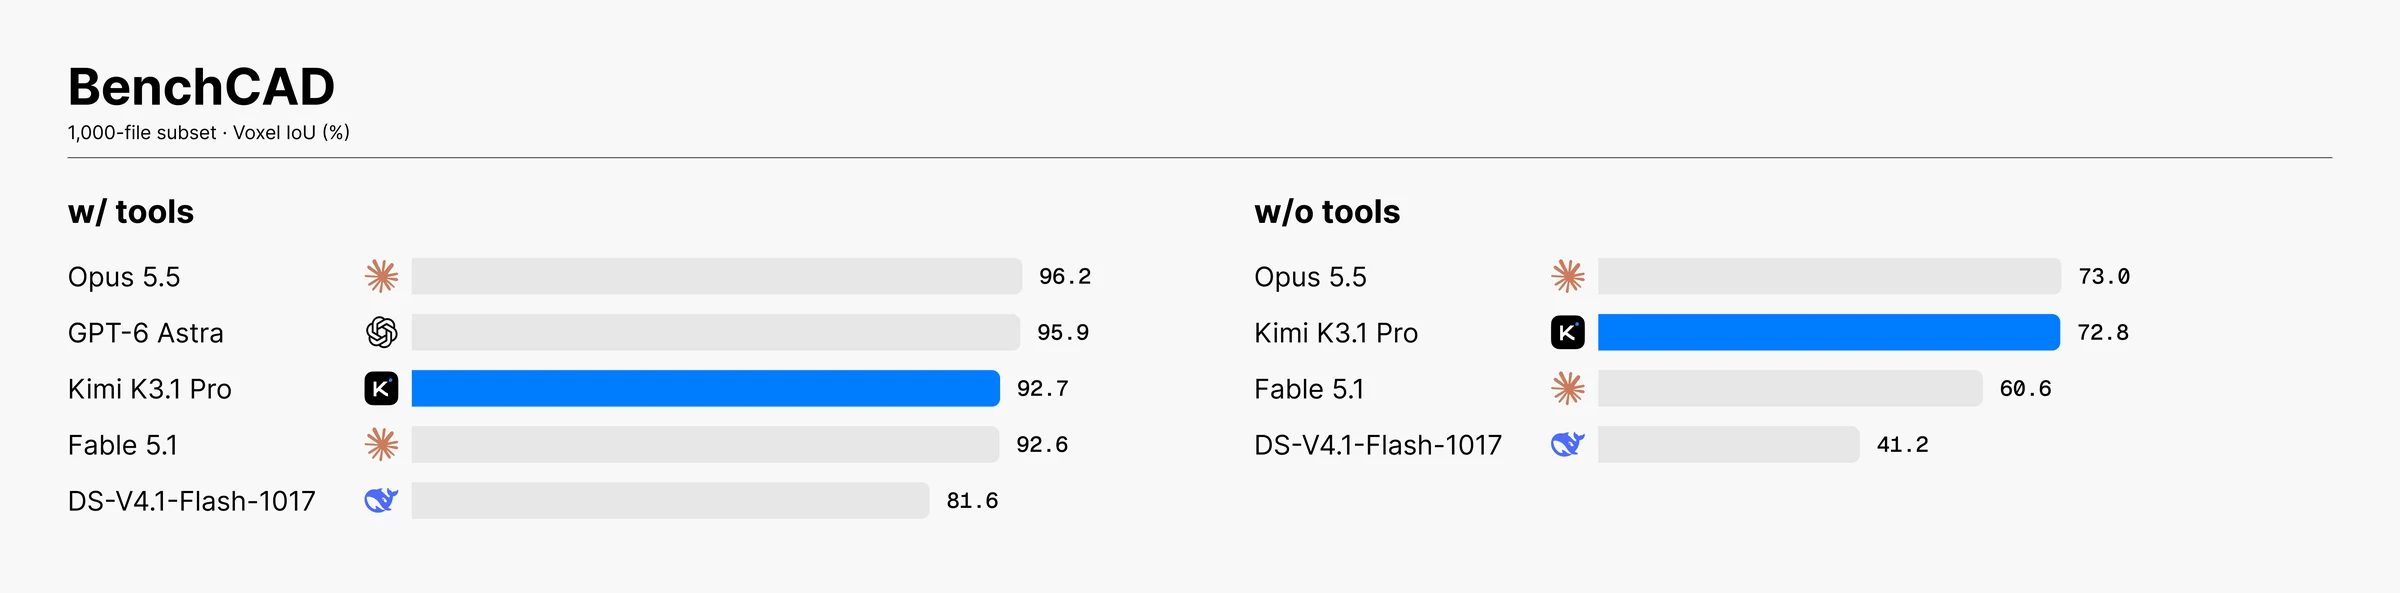
Moonshot AI's BenchCAD comparison, with and without tools. Vendor-reported results.
View full-size chart (opens in a new tab)
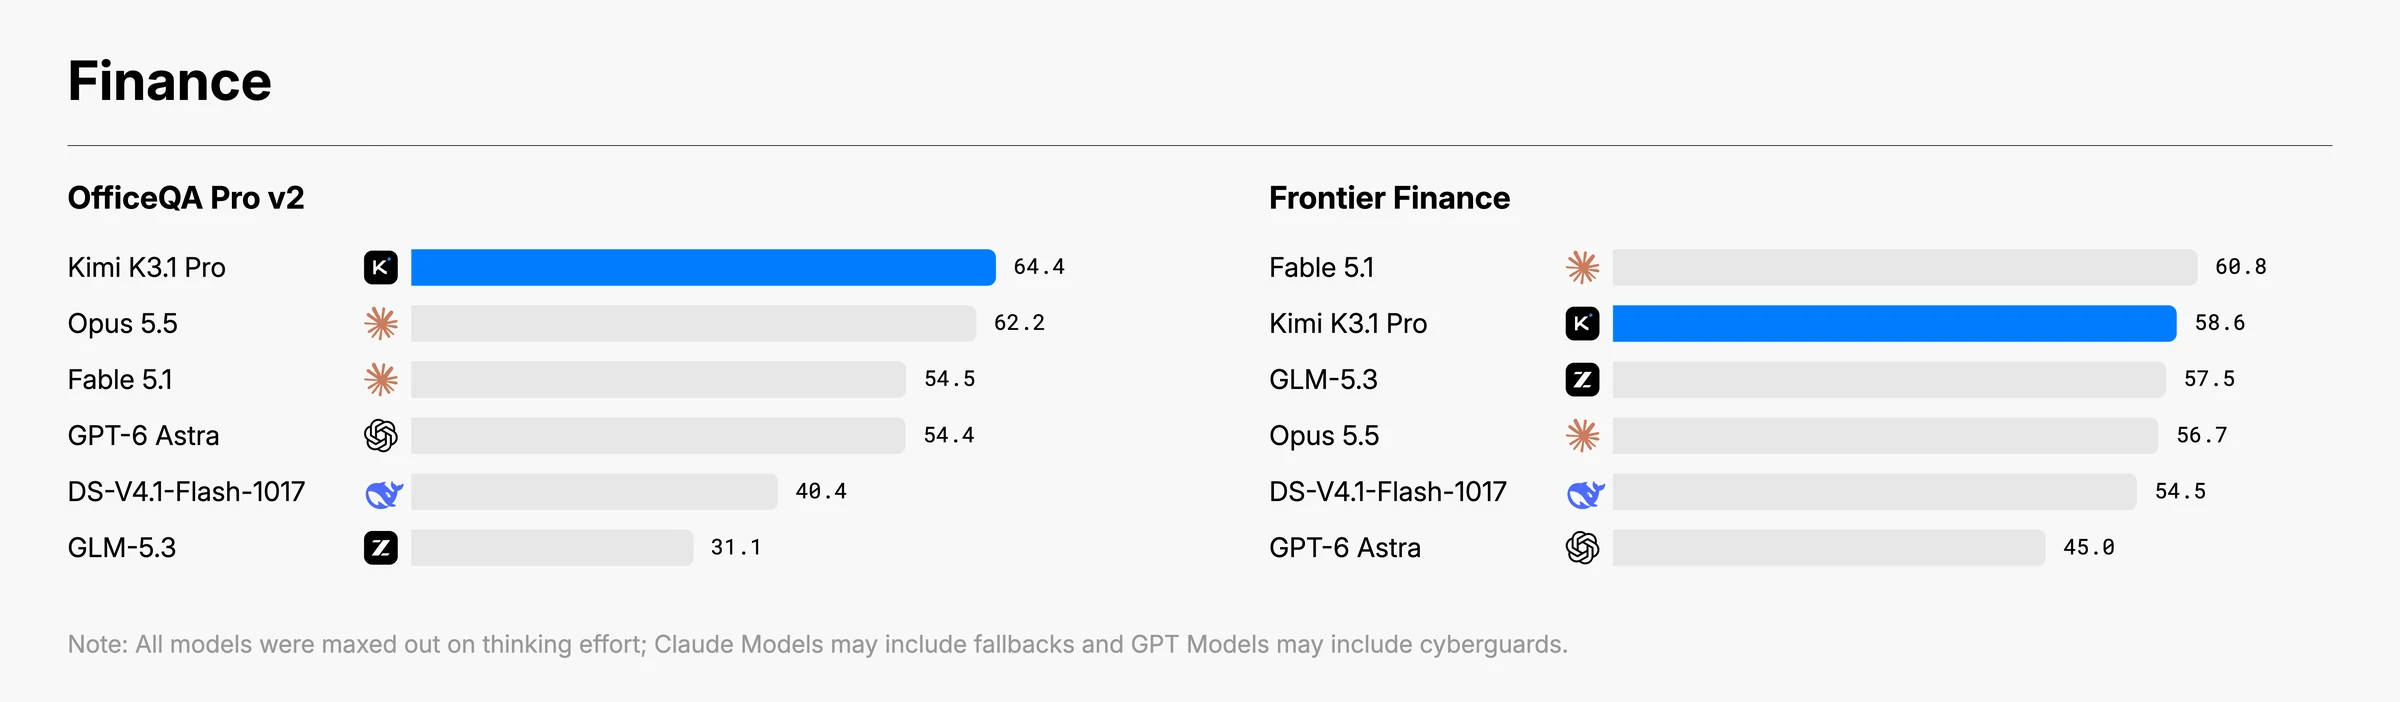
Moonshot AI's OfficeQA Pro v2 and Frontier Finance comparisons. Vendor-reported results.
View full-size chart (opens in a new tab)
Access now, weights later
Moonshot says the full model weights will be released by November 4, 2026. Hosted availability at launch should therefore be distinguished from downloadable weights.
For developers, the practical question is whether the model can sustain useful work across their own code, tools, and constraints.